Reinforcement learning
Learning by trial, error and reward; powers game-playing AI, robotics and the RLHF and reasoning training of modern LLMs.
- 1983
First version
Andrew Barto and Richard Sutton
Image: University of Massachusetts Amherst (derived from the Commonwealth seal by E. H… · Public domain · Wikimedia Commons ('Old seal of the University … - 1988
Temporal-difference learning (Sutton)
Learns predictions from successive estimates rather than final outcomes.
Image: Original: GTE Vector: Opertinicy · Public domain · Wikimedia Commons - 1989
Q-learning (Watkins)
Model-free method to learn optimal action values.
Image: Unknown author · CC BY-SA 3.0 · Wikimedia Commons - 1992
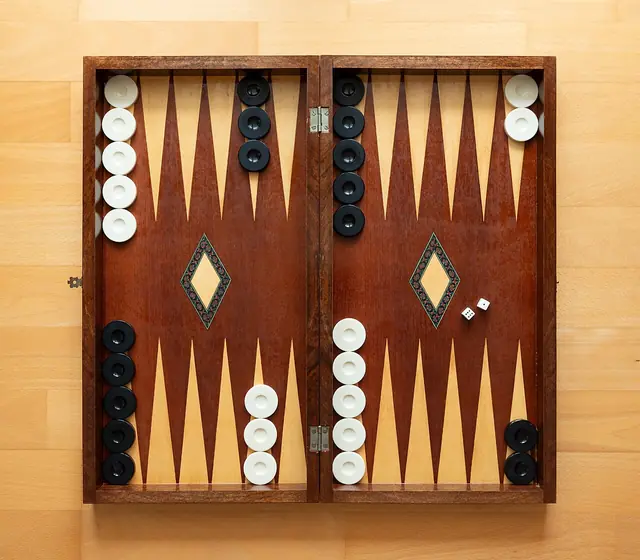
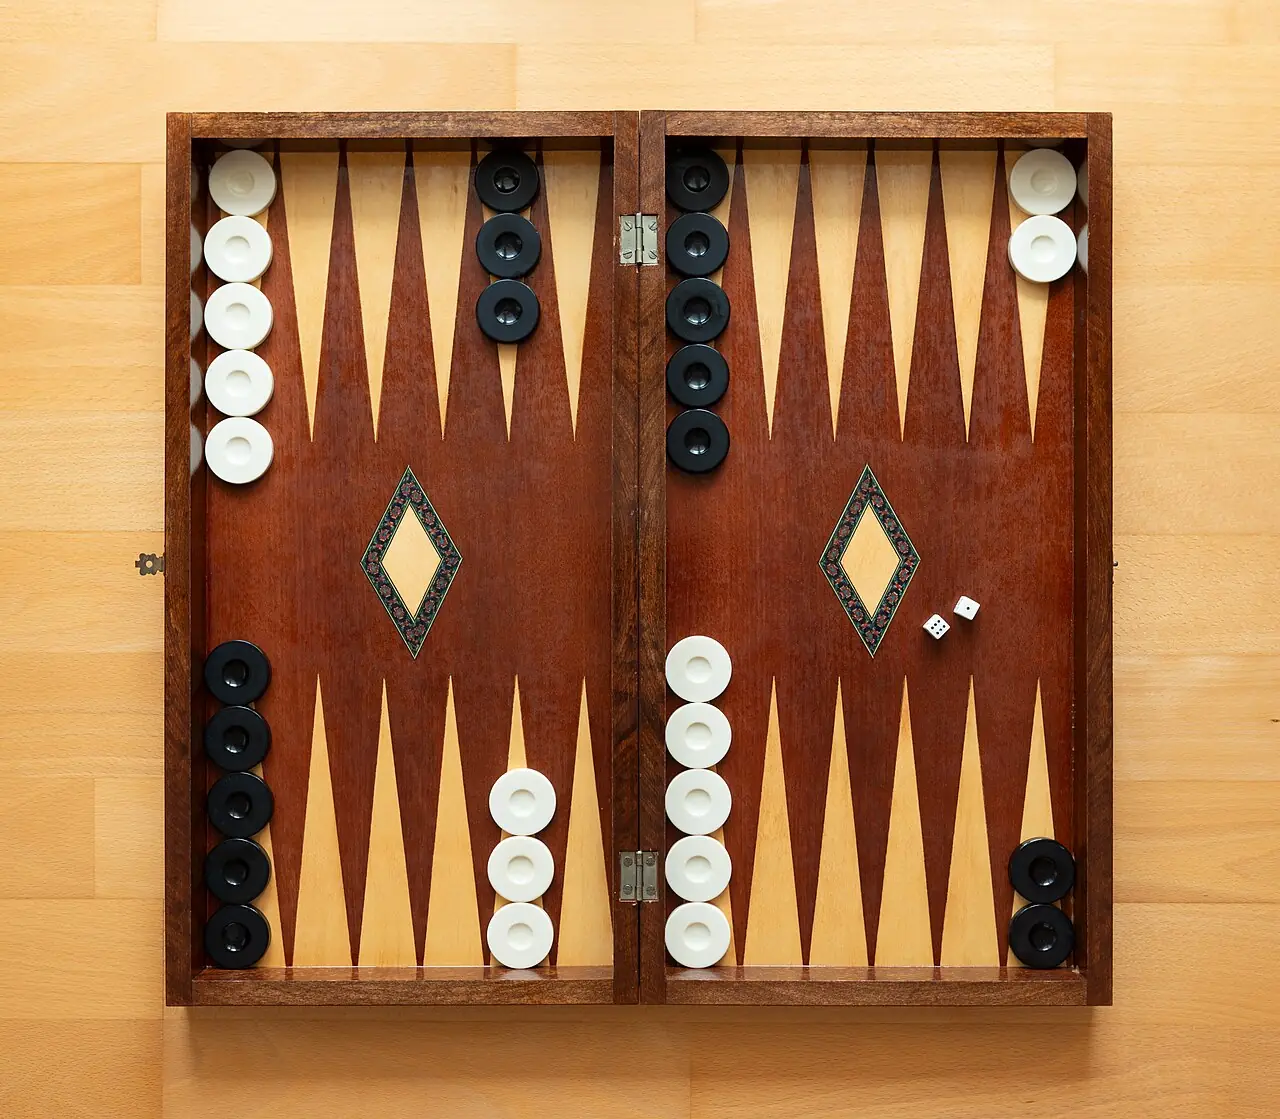
TD-Gammon (Tesauro, IBM)
Self-play TD learning reaches near-champion backgammon.
Image: Nikos Kitsakis · CC BY 4.0 · Wikimedia Commons - 2013
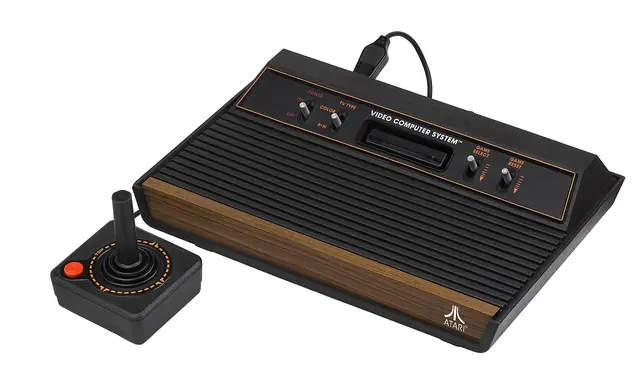
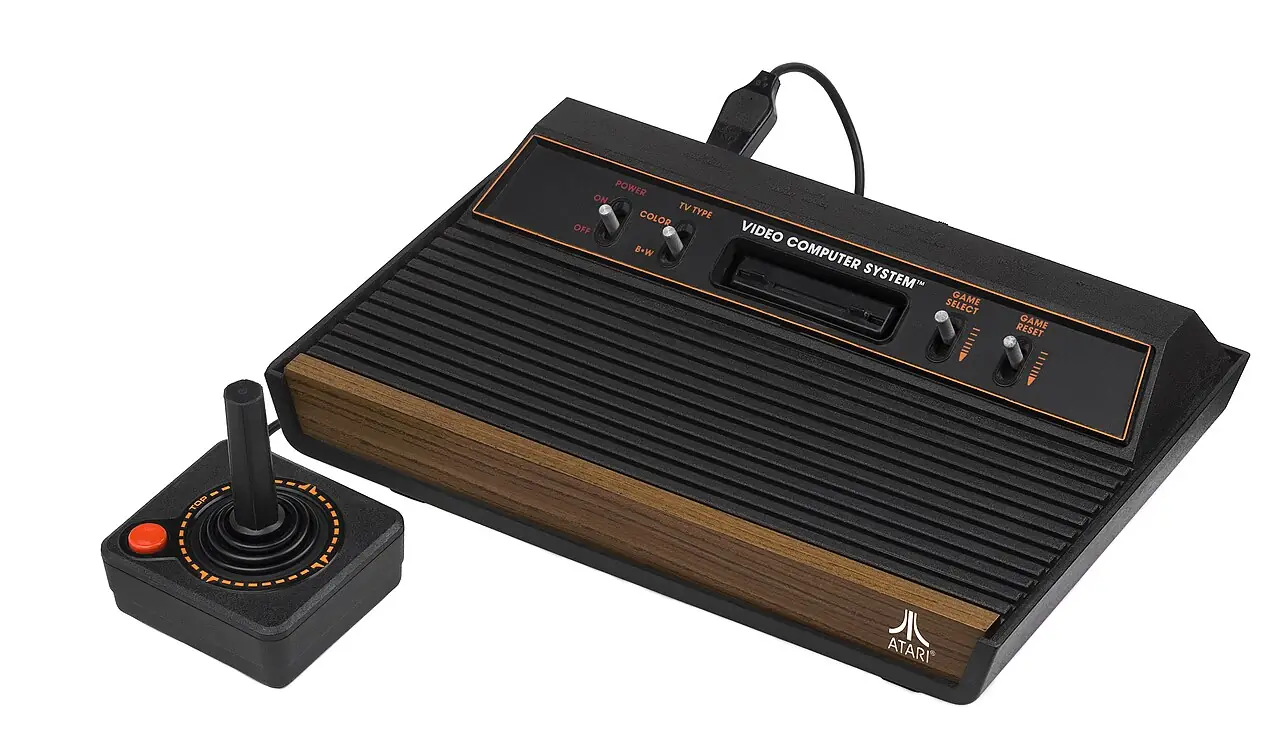
Deep Q-Network (DeepMind)
Deep RL learns to play Atari games straight from screen pixels: 7 games in 2013, 49 in the 2015 Nature paper.
Image: Evan-Amos · Public domain · Wikimedia Commons - 2022
RLHF (InstructGPT/ChatGPT)
Human-feedback rewards align language models; enables ChatGPT.
Image: Unknown author · CC BY 3.0 · Wikimedia Commons - 2025
RL for reasoning (DeepSeek-R1)
Pure RL with checkable rewards teaches language models long step-by-step reasoning, published openly.
Image: High-Flyer · Public domain · Wikimedia Commons


Contested: Builds on Bellman's dynamic programming (1957), Samuel's checkers (1959) and Michie's MENACE (1961); the 2024 Turing Award credits Barto and Sutton.