Deep learning
Training many-layered neural networks on big data and GPUs; from 2012 it overtook other methods in vision, speech and language.
- 2006
First version
Geoffrey Hinton, Yann LeCun, Yoshua Bengio and others
Image: University of Toronto · Unclear; no licence stated (university logo, trademark) · Wayback Machine capture of utoronto.ca, 1 Jul 2006 (site header background image) - 2012
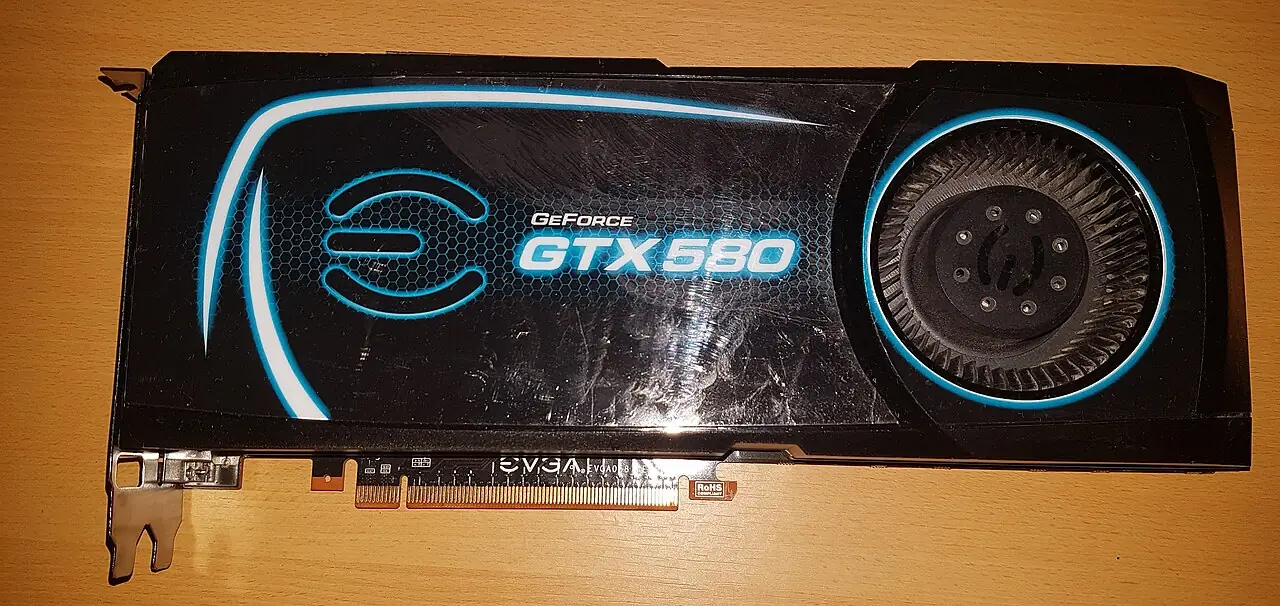
AlexNet
GPU-trained CNN wins ImageNet with 15.3% top-5 error vs 26.2%, igniting the boom.
Image: TheStriker · CC BY-SA 4.0 · Wikimedia Commons - 2015
ResNet (Microsoft Research)
Residual connections enable 152-layer networks; 3.57% ImageNet error.
Image: Microsoft Research · Unclear; no licence stated (© Microsoft) · Wayback Machine capture of research.microsoft.c… - 2017
Transformer architecture
Attention replaces convolution and recurrence, becoming deep learning's dominant architecture for language, images and more.
Image: FritzchensFritz · CC0 · Wikimedia Commons


Contested: Ivakhnenko trained deep networks in 1965; Schmidhuber disputes the Turing Award trio's credit for originating deep learning.