Transformer architecture
'Attention Is All You Need' replaced recurrence with parallel self-attention, the architecture behind virtually every modern language, image and video model.
- 2017
First version
Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan Gomez, Łukasz Kaiser, Illia Polosukhin (Google)
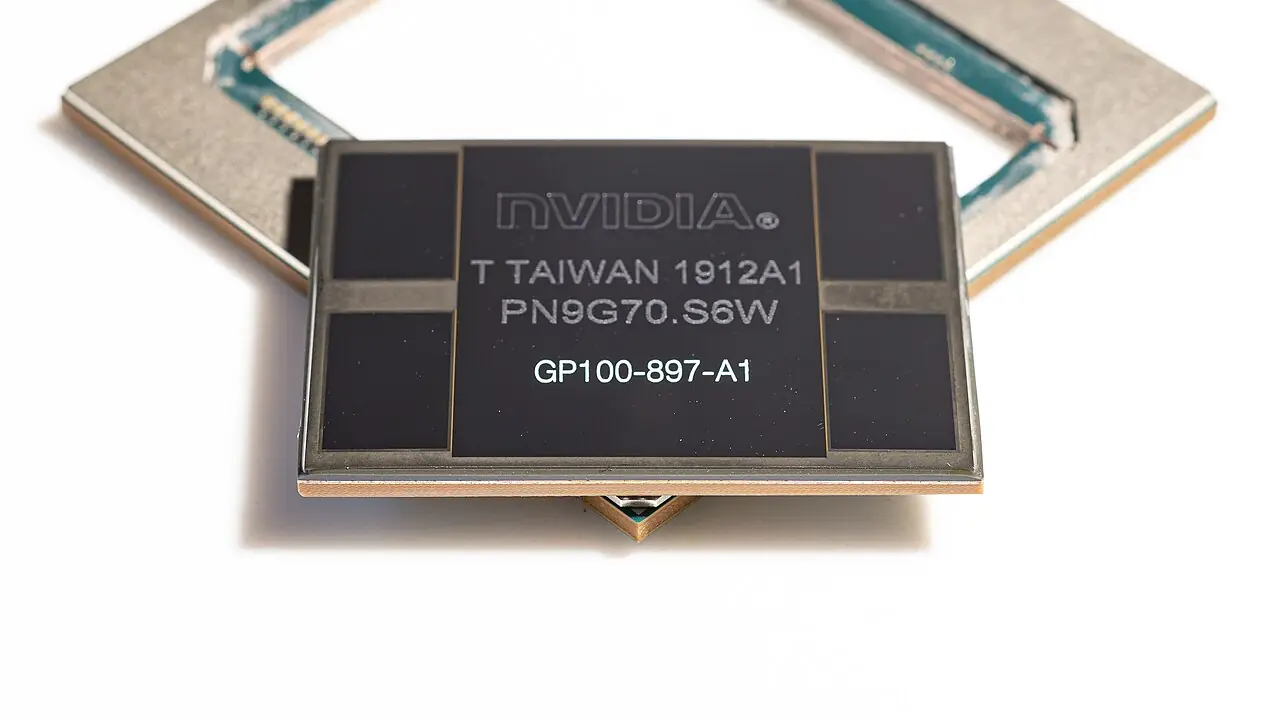
Image: FritzchensFritz · CC0 · Wikimedia Commons - 2018
BERT (Google)
Bidirectional pretraining transforms NLP benchmarks and search ranking.
Image: Google · Copyright Google, all rights reserved · Google Cloud, preserved by the Internet Archive - 2020
Vision Transformer (ViT)
Treats image patches as tokens; transformers spread to vision.
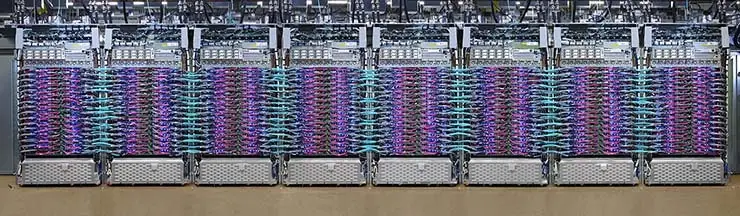
Image: Google · Copyright Google, all rights reserved · Data Center Frontier, credited to Google - 2021
Sparse mixture-of-experts (Switch Transformer)
Routing each token to one of many expert sub-networks lets models reach a trillion parameters at constant compute per token; DeepSeek-V3 (2024) later uses it at the frontier.
Image: Google LLC · Public domain · Wikimedia Commons